APPTWARE Lab
Big Data Engineering Services
Apptware's big data engineering services process the volumes a standard pipeline was never built to handle: distributed data processing frameworks, real-time streaming, and a scalable big data architecture sized for datasets that keep growing, not a fixed capacity ceiling. The goal isn't processing more data for its own sake, it's keeping the insight flowing as the data does.
PROVEN IMPACT
What clients see once we ship.
60%
Faster data processing with distributed frameworks
45%
Improved system efficiency with optimized data pipelines
50%
Reduction in latency for real-time analytics
Trusted by enterprises
Building what's next


THE BIG DATA PROBLEM
Most big data problems show up as a slowdown, not an outage
A pipeline built for yesterday's data volume doesn't crash when it hits its limit. It just gets slower, until the insight arrives too late to act on.

Single-System Architecture Hitting a Ceiling
A pipeline built to run on one machine works fine at small scale, then can't keep up once data volume outgrows what a single system can process.

Batch Processing Where Real-Time Was Needed
Nightly batch jobs deliver insight a day late for decisions that needed to happen in the moment.

No Monitoring Until Throughput Visibly Drops
Cluster performance degrades gradually as load increases, and without monitoring in place, nobody notices until a dashboard falls hours behind.
WHAT WE BUILD
Big data capabilities, built for scale that doesn't slow down
Our big data engineering services can run end-to-end, from architecture design to a fully deployed processing pipeline, or scale a system you already have that's starting to strain.
Distributed Data Processing
Framework-based, scalable big data architecture that splits the work across a cluster instead of asking one system to carry all of it.
Real-Time Stream Processing
Apache Kafka and Flink-based pipelines for the workloads that need instant, data-driven action, not a batch job that runs overnight.
Data Pipeline Automation
AI-driven ingestion and transformation that keeps pace with data arriving continuously, instead of a manual process someone has to babysit.
Cloud & Hybrid Data Architectures
Multi-environment deployment, sized to where the data actually lives and where compute is cheapest to run it.
High-Performance Storage Solutions
Optimized data lakes and warehouses built to keep query speed from degrading as volume climbs.
Advanced Analytics & AI Integration
Machine learning layered on top of the processed data, extracting insight the raw volume would otherwise bury.
HOW WE WORK
Our big data engineering process
Here's how a big data engagement actually turns an overwhelmed pipeline into an ecosystem that scales, phase by phase.
Requirement Analysis & Architecture Design
Real data volume, velocity, and variety get analyzed before any framework gets chosen, so the architecture is scoped for what the business actually generates, not a reference design built for a different scale.
DELIVERABLES
- Data volume, velocity, and variety assessment
- Distributed architecture design and framework selection
- Current-state bottleneck analysis
- Defined performance and latency targets
- Cloud vs. hybrid deployment recommendation
- Prioritized implementation roadmap
Our Methodology
Why validation is non-negotiable for big data engineering
An architecture that performs well on a sample dataset can still fall over at production scale. Every big data engineering engagement we run tests against real volume before the system is treated as production-ready.

Validated at Production Scale, Not Sample Data
Performance gets measured against real data volumes and velocities, so results reflect what happens once the system carries its full workload.

Bottlenecks Audited, Not Assumed Away
Resource constraints and cluster limits get surfaced during architecture design, before implementation starts, not discovered mid-deployment.

Business Latency Requirements First, Framework Elegance Second
A pipeline that's technically sound but doesn't hit the latency the business actually needs gets reworked, not shipped as done.

Monitoring Built Into the Timeline
Each phase closes with a decision on what to tune next, so throughput doesn't quietly decay as data volume grows.
DATA ENGINEERING PRACTICE
Big data pipelines, engineered to stay fast after launch
Most of the risk in a big data project isn't the first deployment, it's whether the cluster still keeps up once data volume has tripled. Getting that wrong is expensive to fix once every downstream system is already depending on the pipeline.
Those calls get made deliberately, as part of the architecture, not discovered after throughput drops.

Reproducible Pipelines
Every processing job is versioned and reproducible, so a performance regression's cause isn't a mystery the first time someone asks what changed.

Scalability Standards
Architecture is designed to scale horizontally from day one, so growth means adding nodes, not a rebuild.

Documentation
Every architecture and framework decision is recorded, so the reasoning behind the design doesn't live in one engineer's head.

Failure Detection by Design
Monitoring for node failures, backpressure, and latency spikes is scoped in at build time, not added after the cluster has already fallen behind.

Performance Benchmarking
Systems get load-tested against real production volumes and concurrent workloads, not a demo-scale sample.

Compliance Readiness
For regulated industries, data governance and audit trail requirements get built into the pipeline from the start, not discovered during a pre-launch review.
TECHNOLOGY STACK
Leading technologies behind our big data pipelines
The stack isn't fixed. Data volume, velocity, and latency requirements decide the tools, not a default template.
Apache Spark
Distributed batch and stream processing, the core engine behind most large-scale data transformations in this practice.
Cluster-basedHadoop / HDFS
Distributed storage for datasets too large for a single system to hold efficiently.
On-premise or cloudApache Kafka / Flink
Real-time stream processing for workloads that need instant, event-driven action.
Low-latencySnowflake / BigQuery
The structured storage layer big data pipelines feed into for querying and reporting.
Managed cloudNo vendor lock-in. Stack selection is driven by data volume and latency needs, not our default template.
Orchestration
Visualization
Cloud & DevOps

THE ROI CASE
The business value delivered by big data engineering services
The payoff doesn't show up in the size of the cluster. It shows up in how fast insight moves from raw data to a decision someone actually acts on.

Faster processing turning raw volume into usable insight sooner

Lower infrastructure costs from optimized resource allocation

Reduced latency for the real-time decisions that depend on it

Higher system efficiency freeing engineering time for new work

Scalable architecture that grows with data volume instead of against it

Fewer outages from pipelines built for real production load

Data visibility shared clearly across teams instead of siloed with one

Lower total cost of ownership than a patchwork of point solutions
Vertical Focus
Big data engineering built for how each industry actually runs
Data volume and velocity look different depending on the industry, and so does the cost of a pipeline that can't keep up. Healthcare, BFSI, and manufacturing generate data at a scale a generic pipeline wasn't built to handle.
Patient and device data, processed at volume
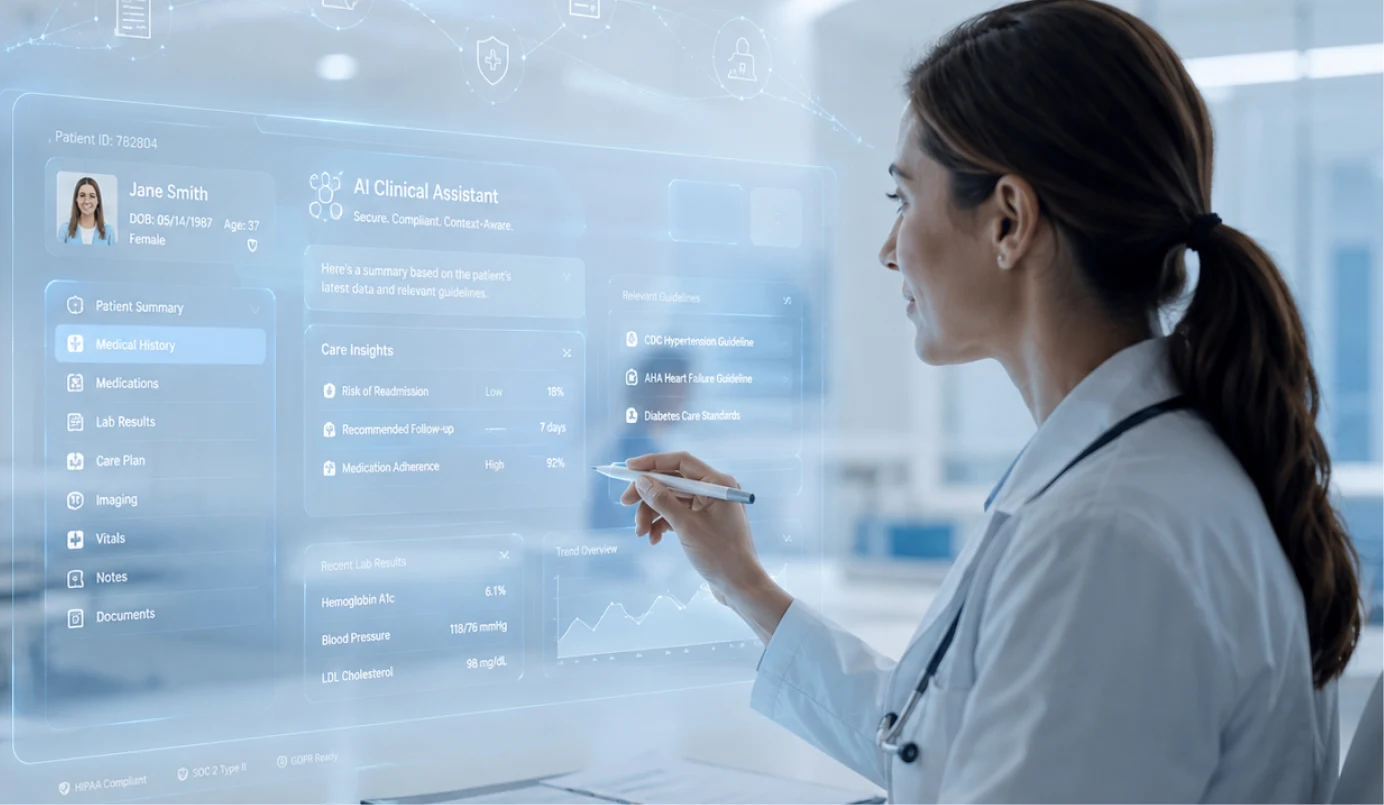
- Distributed processing for continuous patient monitoring data streams
- High-volume clinical and imaging data pipelines
- Real-time alerting from connected medical device data
- Scalable storage for growing population health datasets
Transaction data, processed without falling behind
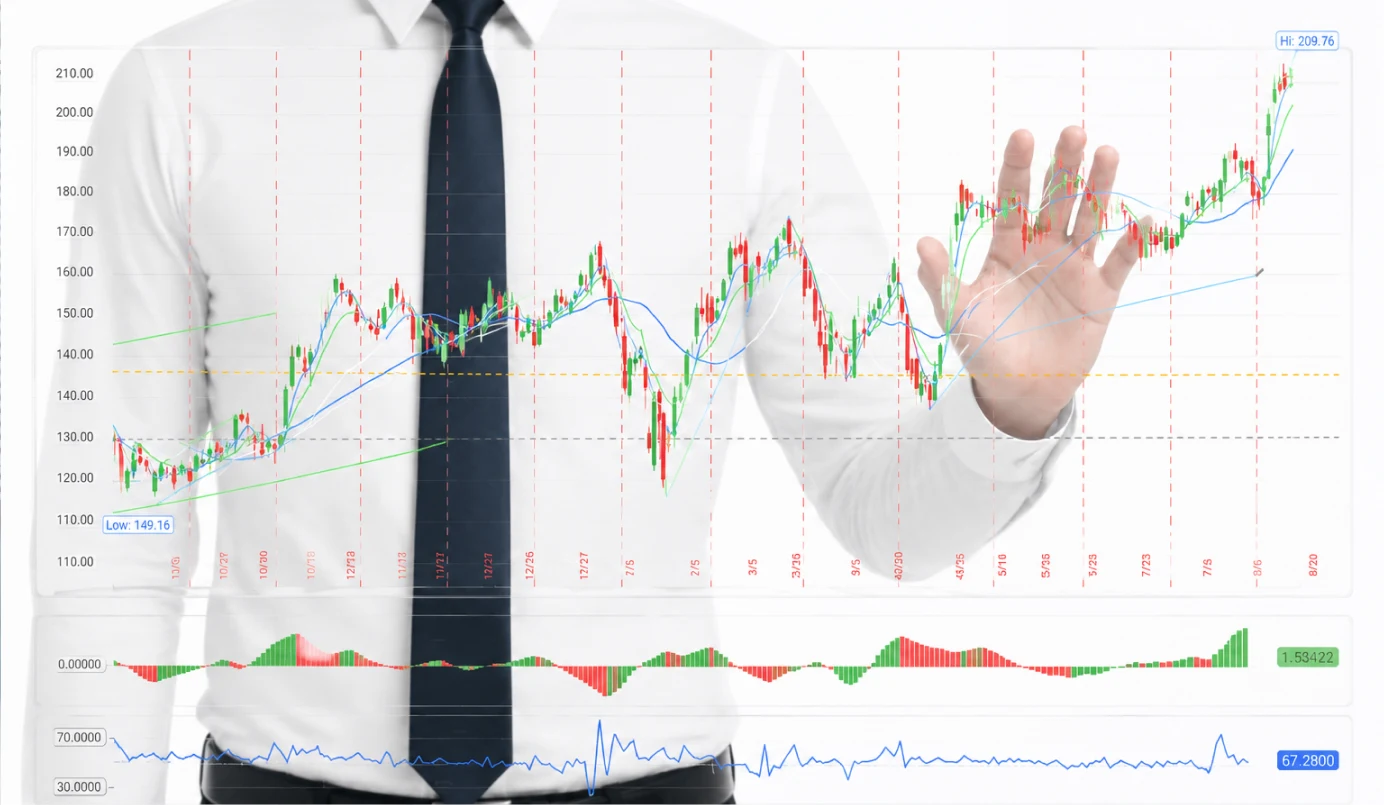
- Real-time fraud detection on high-velocity transaction streams
- Distributed processing for market and trading data at scale
- High-throughput pipelines for regulatory reporting datasets
- Scalable architecture for growing customer transaction volumes
Connected vehicle data, processed continuously
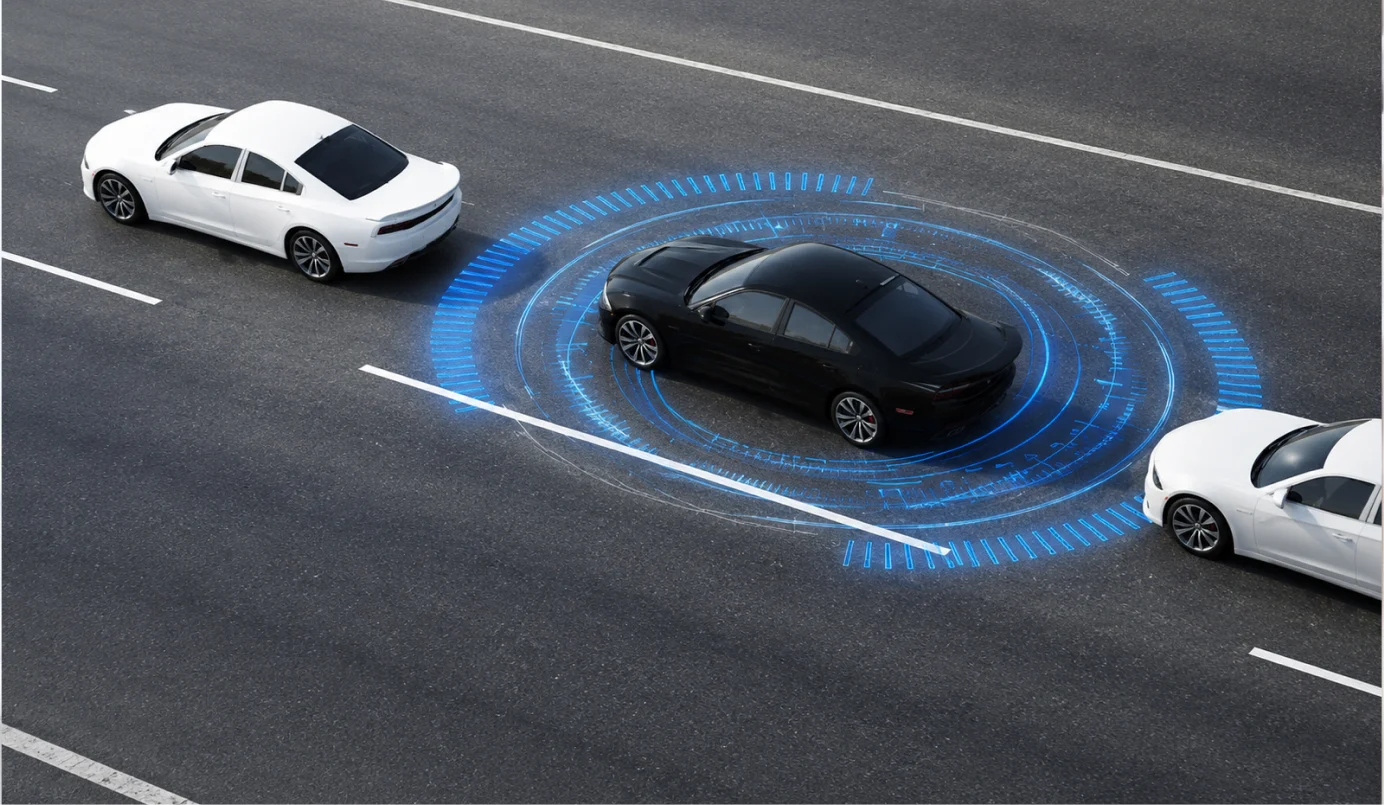
- Real-time telematics processing from connected vehicle fleets
- Distributed pipelines for sensor data across production lines
- High-volume warranty and service data processing
- Scalable architecture for growing fleet data volumes
Sensor data, processed as it's generated
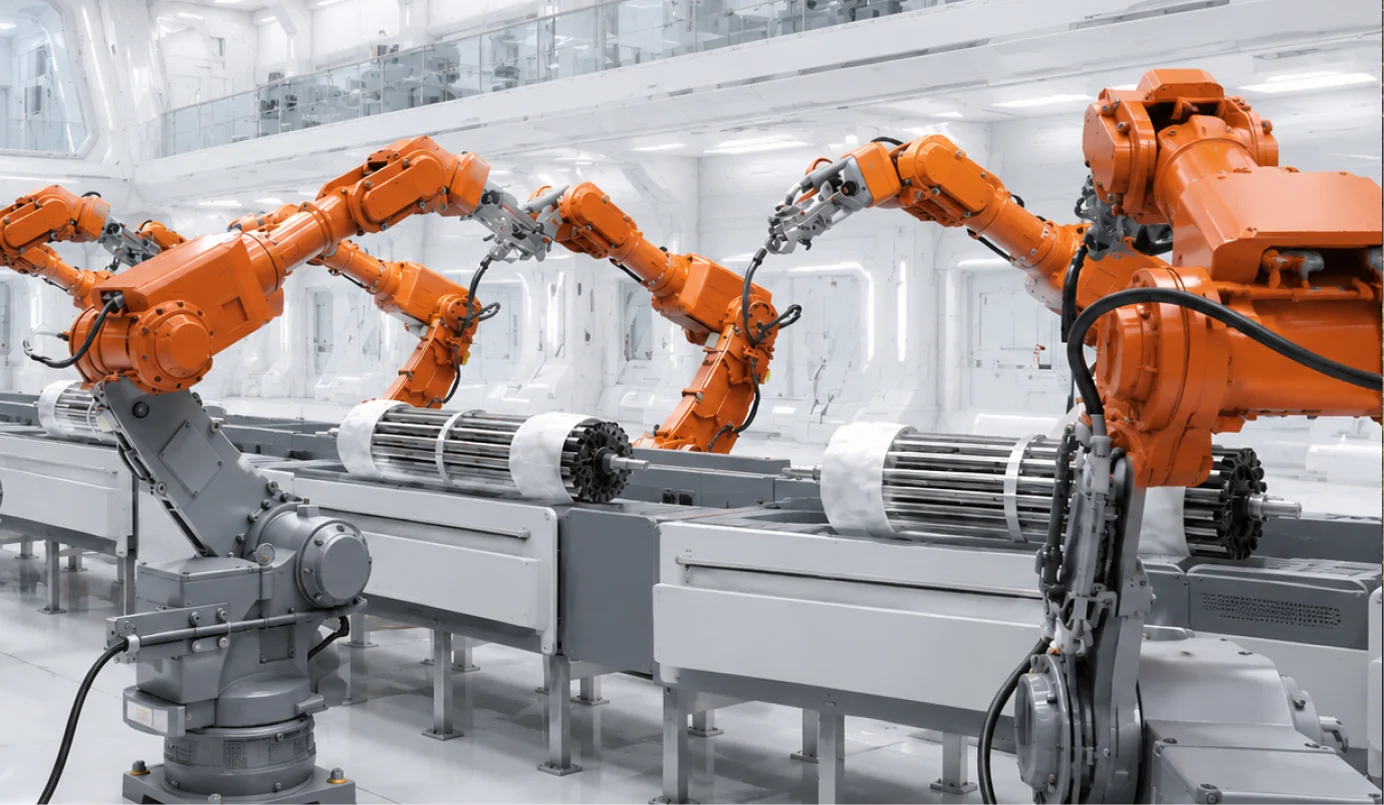
- Real-time processing of shop-floor sensor and equipment data
- Distributed pipelines for supply chain data at scale
- High-throughput quality and defect data processing
- Scalable storage for growing production data volumes
Field and sensor data, processed at scale
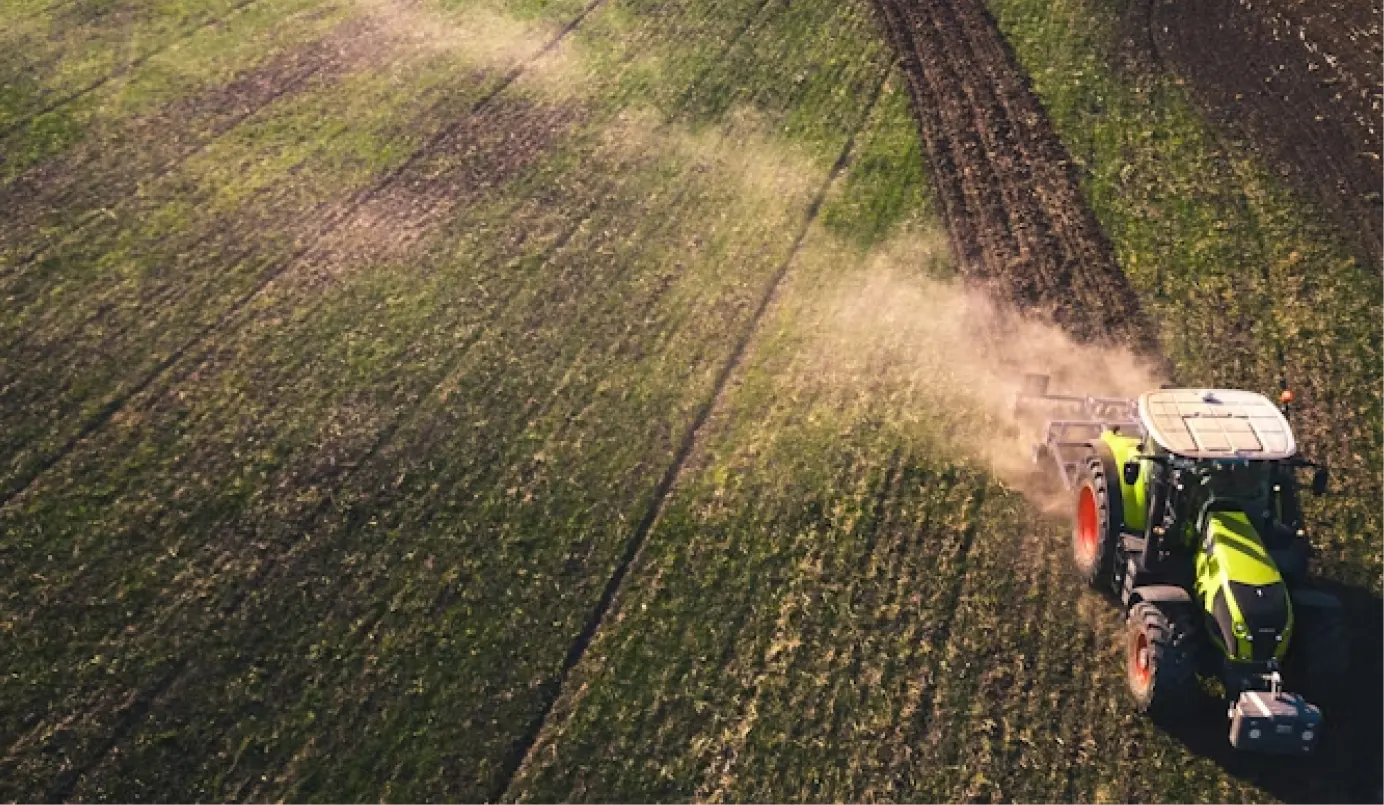
- Distributed processing for field sensor networks across large operations
- Real-time pipelines for weather and satellite data streams
- High-volume seasonal data processing across growing regions
- Scalable architecture for expanding sensor deployments
Transaction and behavior data, processed continuously
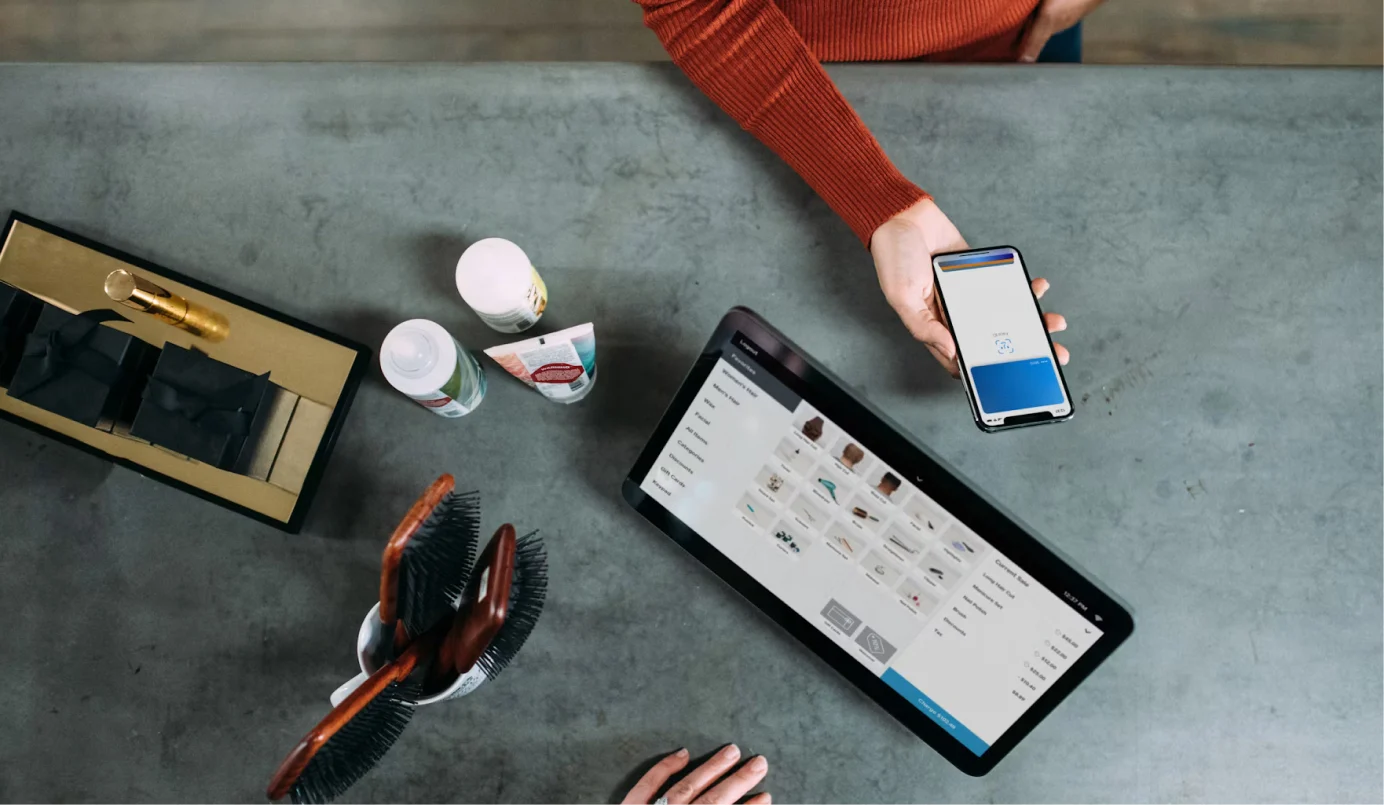
- Real-time processing of point-of-sale data across channels
- Distributed pipelines for customer behavior data at scale
- High-throughput inventory data processing across locations
- Scalable architecture for peak-season traffic volumes
WHY US
What makes Apptware a big data engineering partner
Plenty of teams can stand up a cluster that processes data on day one. What matters is whether it still keeps up once volume triples, and that shows up in how the engagement is built, not just in the first demo.
01
Fixed-Scope Discovery
Whether you engage us for a single pipeline or a full big data architecture build, the discovery phase is scoped upfront, what gets evaluated, how long it takes, and what you'll have in hand at the end.
02
Working Pipeline, Fast
You'll have a working pipeline processing real data volume within the first few weeks, not a diagram describing what the architecture might eventually handle.
03
Validation at Every Phase
Feedback from one phase shapes the scope of the next. If early performance testing changes the plan, the roadmap changes with it, mid-project, not just at a single review gate.
04
Support After Launch
A deployed big data pipeline still needs monitoring and tuning as volume grows. Our team stays on to track performance and ship the optimizations it points to.

Apptware Solutions' work helped the client improve their time-to-market. The team retained all core resources throughout the contract. Apptware Solutions assigned a project manager to oversee the tasks and timelines. The team was proactive in communicating and responding to the client.

Get Started
Ready for a pipeline that
scale with your data?
Tell us where volume is outgrowing your current setup. Whether you need a single distributed pipeline or a full big data architecture, we'll run the data feasibility check, map out the build and timeline, and give you a real cost estimate before any development work starts.
 No-cost discovery audit
 100% IP ownership
 No commitment required
 US & India presence
FAQ'S
Straight answers to what prospective clients ask most before committing to a discovery phase.
If your current pipeline is slowing down, timing out, or requiring bigger and bigger servers just to keep pace, that's usually the sign a distributed architecture would solve what vertical scaling can't.
Let's talk about the data that isn't syncing yet
Need expert guidance on connecting the systems that aren't talking to each other? Spend 45 minutes with our data engineering team. They'll audit your current sources, benchmark what a pipeline build would take, and return a roadmap with timeline and cost, within 5 business days, no commitment.
 USA
 INDIA
Got a similar challenge?
Is your current pipeline buckling under real data volume?
Let's talk about what Apptware can build for you.