APPTWARE Lab
Data Integration & ETL Pipeline Services
Apptware builds the ETL pipelines that keep every system in your stack working from the same data, instead of each team reconciling its own export. Structured and unstructured sources get extracted, transformed, and loaded through pipelines engineered for consistency and security, with real-time availability where the business actually needs it.
PROVEN IMPACT
What clients see once we ship.
90%
Data accuracy with automated validation
70%
Reduction in manual processing time
50%
Faster data integration across systems
Trusted by enterprises
Building what's next


THE DATA INTEGRATION PROBLEM
Most integration problems get discovered downstream, not at the source
A broken pipeline rarely announces itself. It shows up as a report that doesn't match, weeks after the actual data started drifting.

Point-to-Point Integrations That Don't Scale
Each new source gets its own custom connection, until the integration layer is more fragile than the systems it connects.

Manual Exports Standing In for Pipelines
A spreadsheet export someone remembers to run each week is doing the job a real pipeline should be doing automatically.

No Validation Between Extraction and Load
Bad data moves through the pipeline just as fast as good data, so problems surface in a report instead of at the source.
WHAT WE BUILD
Data integration capabilities, built around your systems
Our data integration and ETL pipeline services can run end-to-end, from source connection to a governed, always-current dataset, or plug into a pipeline you already have.
Automated ETL Workflows
Extraction, transformation, and loading pipelines built for structured and unstructured data alike, running on a schedule instead of a manual export someone has to remember.
Seamless Data Integration
Every source your business actually runs, APIs, databases, and cloud platforms included, connected into one pipeline instead of a dozen point-to-point exports.
Real-Time Data Processing
Low-latency transformation for the systems that need current data now, not the next scheduled batch run.
Data Cleansing & Enrichment
Inconsistencies get caught and corrected in the pipeline itself, so downstream teams aren't cleaning the same data twice.
Scalable Architecture
Cloud-native or on-premise, sized for data volumes that keep growing instead of a fixed capacity ceiling.
Data Security & Compliance
Encryption and access controls built into how data moves, not added after it lands somewhere unprotected.
HOW WE WORK
Our data engineering and analytics process
Here's how a data integration engagement actually turns scattered sources into one reliable pipeline, phase by phase.
Assessment & Strategy
Every data source that actually matters gets mapped, including the ones nobody's documented in a while, and a tailored integration plan gets built around what the business needs from the data, not a generic template.
DELIVERABLES
- Data source audit and integration map
- Current-state data flow and gap assessment
- Data quality baseline report
- Defined transformation and validation rules
- Security and compliance requirements review
- Prioritized pipeline build plan
Our Methodology
Why validation is non-negotiable for data integration
A pipeline that moves data without checking it just moves the problem downstream faster. Every data integration and ETL pipeline engagement we run validates data at each stage, because a fast pipeline feeding bad data is worse than a slow one that catches it.

Validated at Every Stage, Not Just at Load
Data gets checked on extraction and after transformation, not only once it lands in the target system, so errors get caught before they spread.

Source Quirks Audited, Not Assumed Away
Each source system's format inconsistencies and edge cases get mapped during discovery, not discovered mid-pipeline when something breaks.

Business Need First, Pipeline Elegance Second
A pipeline that's technically clean but doesn't deliver data in the shape downstream systems actually need gets reworked, not shipped as done.

Monitoring Built Into the Timeline
Each phase closes with a decision on what to tune next, so pipeline performance doesn't quietly decay as source volume grows.
Data Engineering Practice
ETL pipelines, engineered to stay reliable after launch
Most of the risk in a data integration project isn't the first pipeline run, it's whether it still works once a source system changes its schema without warning. Getting that wrong is expensive to fix once downstream reports have already been running on bad data for weeks.
Those calls get made deliberately, as part of the pipeline architecture, not discovered after something breaks.

Reproducible Pipelines
Every pipeline run is versioned and logged, so a data discrepancy's source isn't a mystery the first time someone asks where a number came from.

Failure Detection by Design
Monitoring for source-schema changes and load failures is scoped in at build time, not added after a pipeline has already been silently failing.

Data Lineage Standards
Every transformation is documented and traceable, so a number in a downstream report can be traced back to its original source.

Performance Benchmarking
Pipelines get load-tested against real source-system volumes, not a small sample that looks clean in a demo.

Documentation
Every integration mapping and transformation rule is recorded, so the pipeline logic doesn't live in one engineer's head.

Compliance Readiness
For regulated industries, data handling and audit trail requirements get built into the pipeline from the start, not discovered during a pre-launch review.
Technology Stack
Leading technologies behind our ETL pipelines
The stack isn't fixed. Source variety, data volume, and latency requirements decide the tools, not a default template.
Apache Airflow / dbt
Orchestration and transformation logic for pipelines that need to run reliably on a schedule.
Version-controlled, testablePython / SQL
Extraction and transformation scripting, the core languages behind most ETL logic.
pandas · SQLAlchemyApache Kafka / Spark
Real-time and batch data movement for sources that need low-latency processing.
AWS · Azure · GCPSnowflake / BigQuery / PostgreSQL
The target systems pipelines load into, chosen by data volume and query pattern.
Managed cloud or self-hostedNo vendor lock-in. Stack selection is driven by data volume and latency needs, not our default template.
Data Quality & Validation
Monitoring & Orchestration
Cloud & DevOps

The ROI Case
The business value delivered by data integration services
The payoff doesn't show up in how clean the pipeline code is. It shows up in how much less time teams spend reconciling data that should have matched in the first place.

Faster, more confident decision-making from one consistent dataset

Fewer hours lost reconciling conflicting exports across teams

Reduced compliance risk from encrypted, access-controlled data movement

Lower total cost of ownership than maintaining point-to-point integrations

Higher data accuracy compounding as automated validation catches more

Shorter time from new source onboarding to usable data

Data visibility shared clearly across teams instead of siloed with one

A pipeline architecture that scales with source count instead of breaking at it
Vertical Focus
Data integration built for how each industry actually runs
The sources, formats, and compliance rules look different depending on the industry. A generic ETL template wasn't built to handle what healthcare or BFSI data actually requires.
Clinical data, unified without compromising compliance
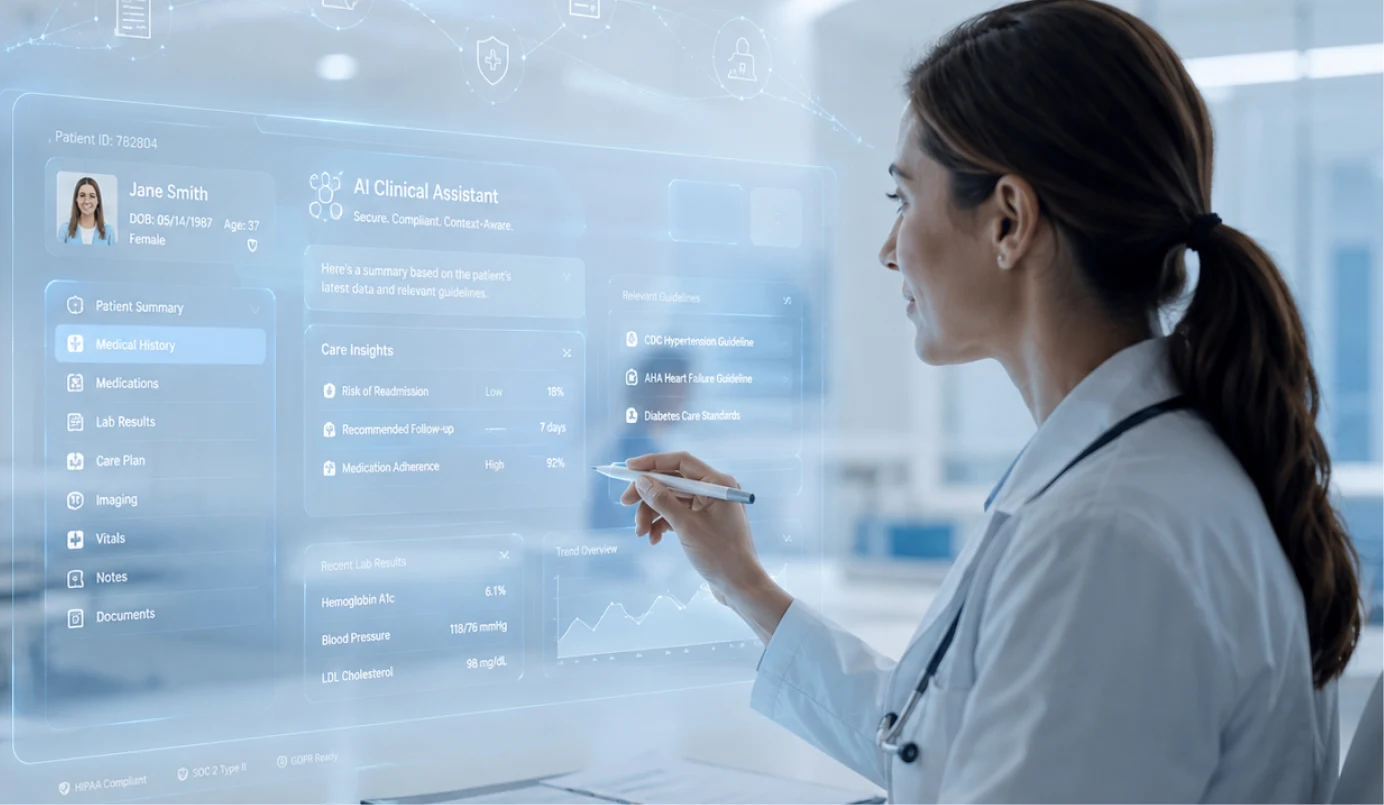
- HIPAA-compliant pipelines across EHR, billing, and lab systems
- Real-time patient data availability across care teams
- Legacy system integration for clinics still running older records platforms
- Automated validation for clinical data accuracy
Transaction data, moved with an audit trail attached
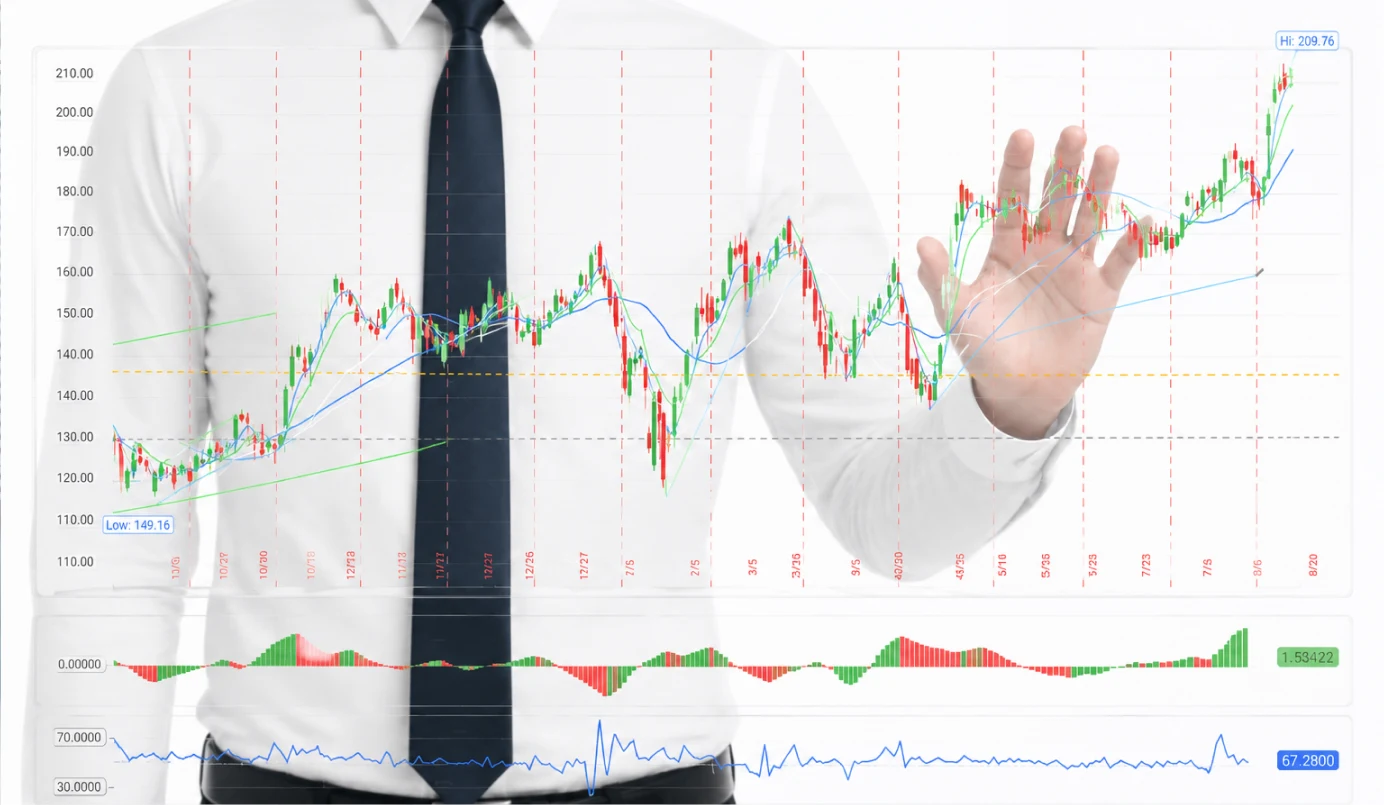
- Real-time transaction pipelines feeding fraud detection systems
- Core banking and third-party API integration
- Encrypted data movement across regulated systems
- Automated reconciliation across accounts and ledgers
Telematics and dealer data, connected end to end
- Vehicle telematics pipelines from connected fleets
- Dealer network data integration across regional systems
- Parts and inventory data synchronized across suppliers
- Warranty and service record consolidation pipelines
Shop-floor and supply chain data, joined together
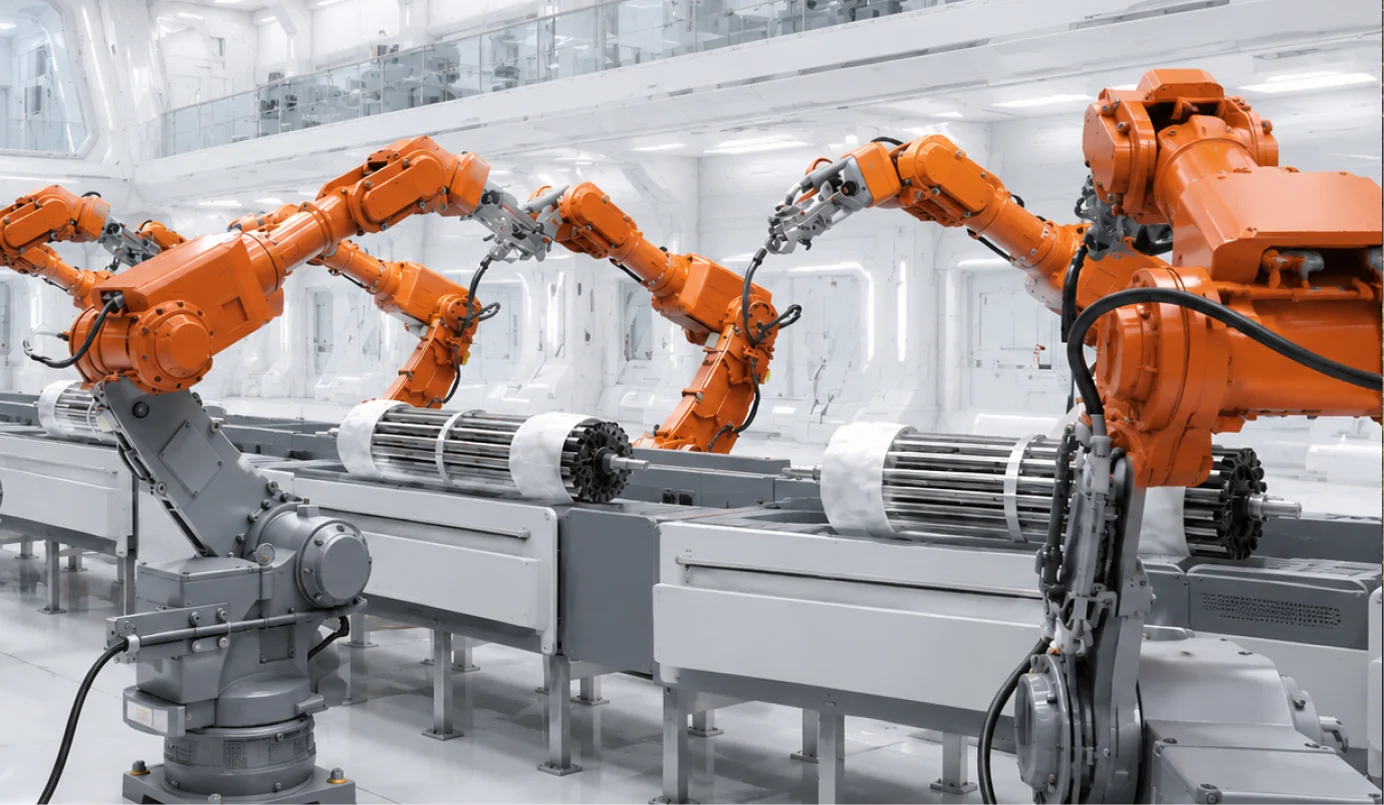
- Sensor and equipment data pipelines from production lines
- Supplier and inventory data integration across plants
- ERP and MES system data synchronization
- Quality control data consolidated for real-time review
Field data, pulled in from wherever it originates
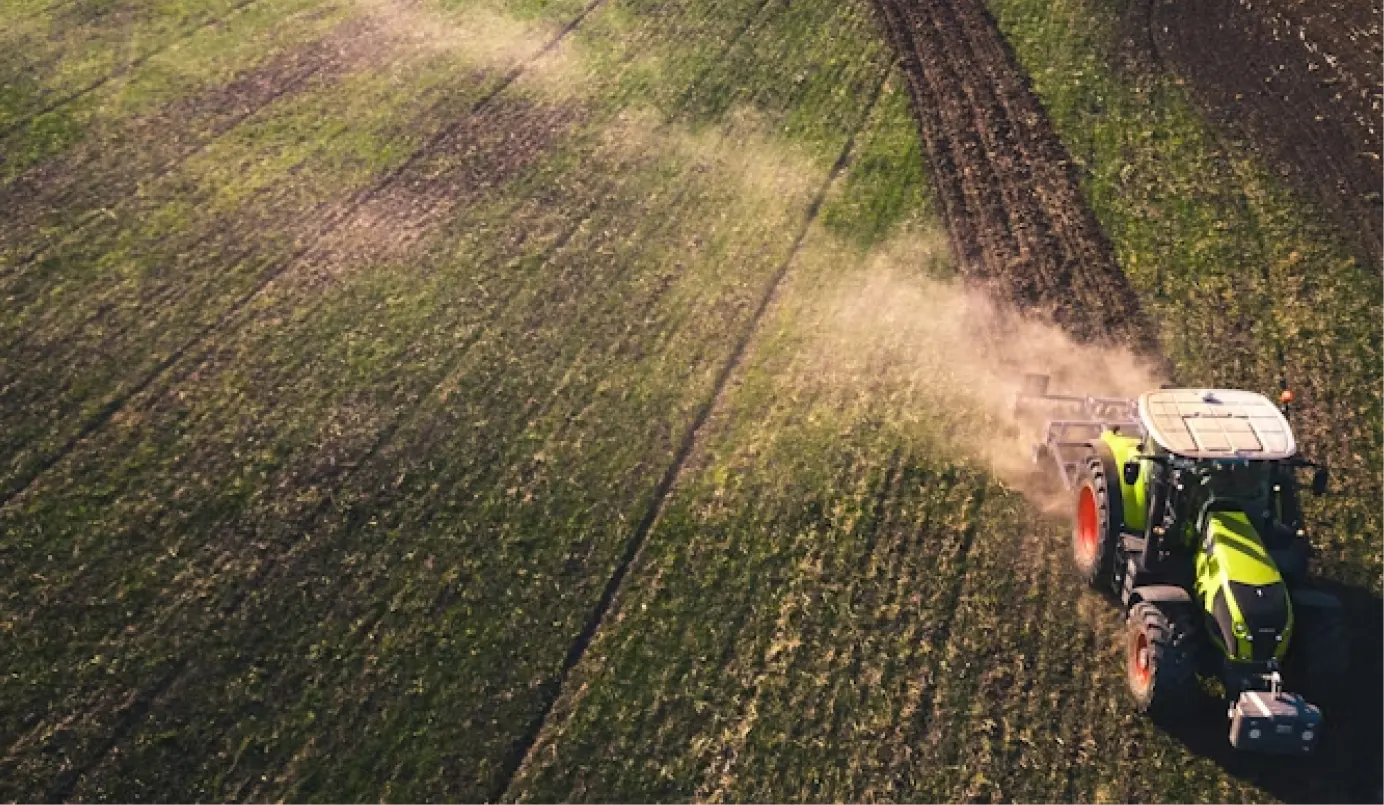
- Field sensor and equipment data pipelines from remote sites
- Weather and satellite data integration for yield models
- Offline-first data sync for low-connectivity field conditions
- Seasonal data consolidation across growing regions
Channel and inventory data, kept in sync
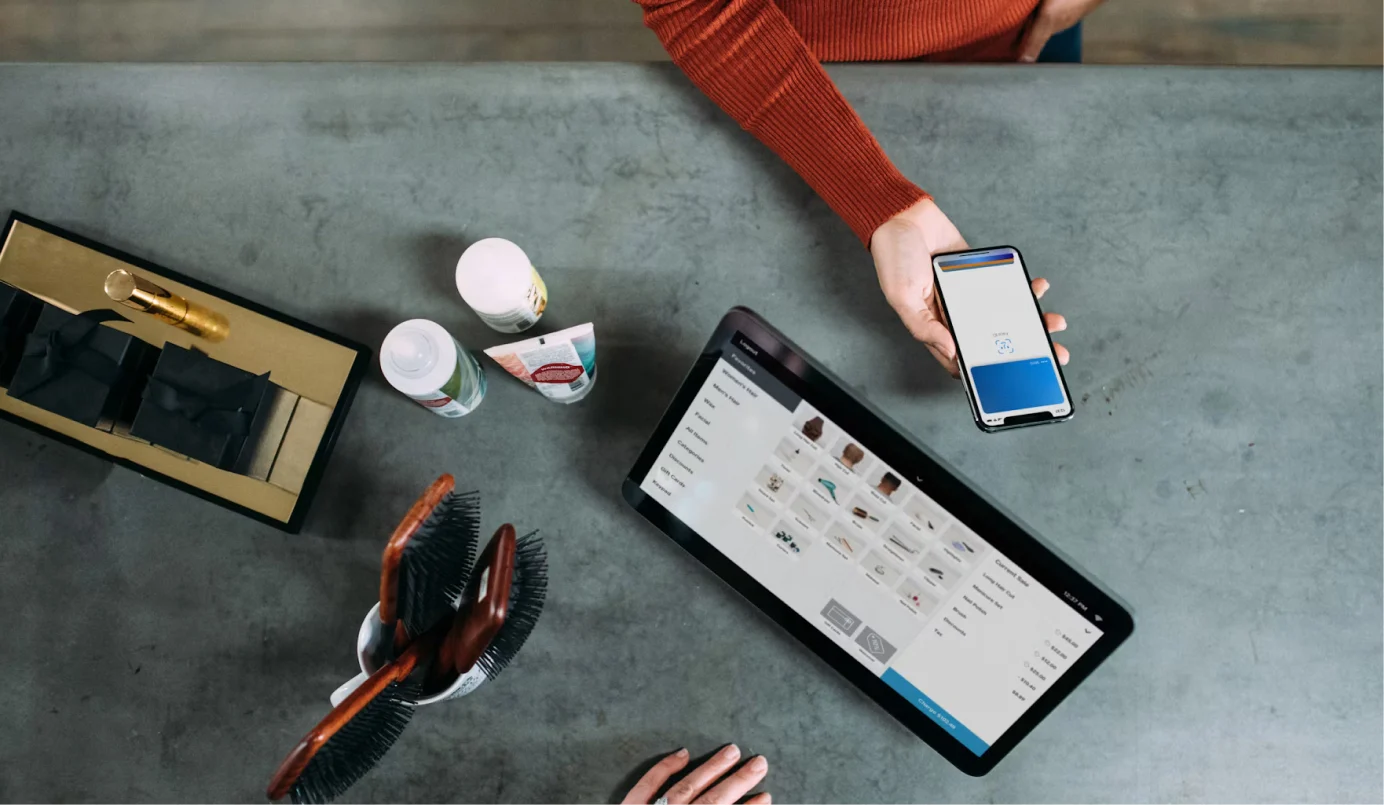
- Point-of-sale and e-commerce data pipelines across channels
- Inventory synchronization between warehouses and stores
- Customer data integration across loyalty and payment systems
- Supplier and logistics data consolidated in real time
Why Us
What makes Apptware a data integration and ETL partner
Plenty of teams can connect two systems together. What matters is whether the pipeline still works once a source changes its schema, and that shows up in how the engagement is built, not just in the first demo.
01
Fixed-Scope Discovery
Whether you engage us for a single pipeline or a full data integration services build, the discovery phase is scoped upfront, what gets evaluated, how long it takes, and what you'll have in hand at the end.
02
Working Pipeline, Fast
You'll have a working pipeline moving real data within the first few weeks, not a diagram describing what an integration might eventually look like.
03
Validation at Every Phase
Feedback from one phase shapes the scope of the next. If early data quality or integration results change the plan, the roadmap changes with it, mid-project, not just at a single review gate.
04
Support After Launch
A deployed pipeline still needs monitoring and a plan for what gets integrated next. Our team stays on to track data quality and ship the fixes it points to.

Apptware Solutions' work helped the client improve their time-to-market. The team retained all core resources throughout the contract. Apptware Solutions assigned a project manager to oversee the tasks and timelines. The team was proactive in communicating and responding to the client.

Get Started
Ready to stop
reconciling data by hand?
Tell us which systems aren't talking to each other. Whether you need data integration consulting to scope the right approach, a single ETL pipeline, or a full data integration services build, we'll run the data feasibility check, map out the pipeline and timeline, and give you a real cost estimate before any development work starts
 No-cost discovery audit
 100% IP ownership
 No commitment required
 US & India presence
FAQ'S
Straight answers to what prospective clients ask most before committing to a discovery phase.
ETL is the mechanism, extract, transform, load. Data integration is the broader goal, getting every system working from consistent data. Most engagements need both, built together as one pipeline.
Let's talk about the data that isn't syncing yet
Need expert guidance on connecting the systems that aren't talking to each other? Spend 45 minutes with our data engineering team. They'll audit your current sources, benchmark what a pipeline build would take, and return a roadmap with timeline and cost, within 5 business days, no commitment.
 USA
 INDIA
Got a similar challenge?
Tired of reconciling data from a dozen different sources?
Let's talk about what Apptware can build for you.